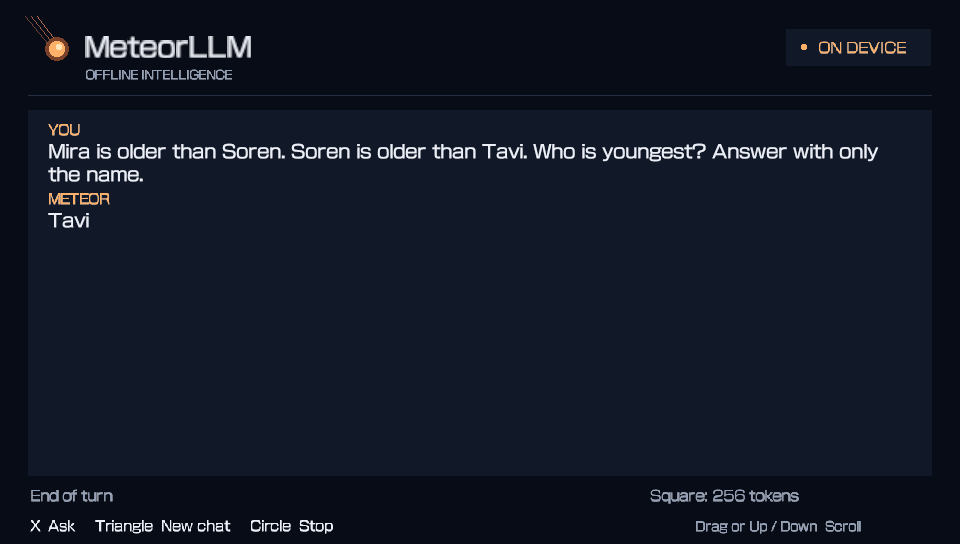
MeteorLLM runs a 0.6-billion-parameter chatbot offline on PS Vita
MeteorLLM v0.1.2 runs the Qwen3-0.6B language model fully offline on PS Vita, with faster replies and a scrollable chat.
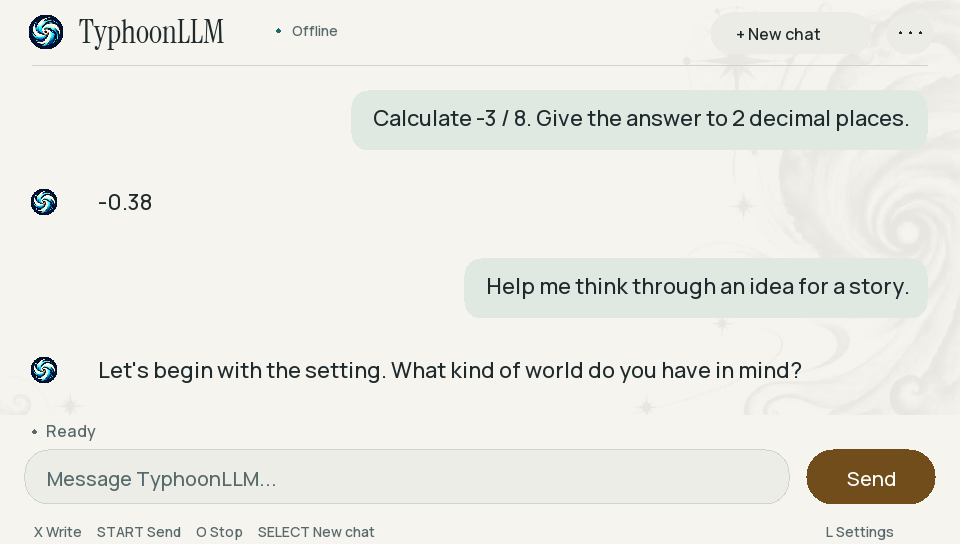
MeteorLLM v0.1.2 runs Qwen3-0.6B, a language model with 0.6 billion parameters, fully on the PS Vita. Replies are generated on the handheld, with no server or internet connection involved. The project follows TyphoonLLM, an earlier Vita build that ran a 230M-parameter model.
Fitting a model about 2.6 times larger on the same hardware needed some tricks. Meteor keeps the transformer weights in RAM and streams the output weights from storage. The first working build took nearly 12 minutes to answer a short ordering question. After splitting the work across three CPU workers and processing prompt tokens in batches, the same test took 2 minutes 16 seconds. That run used the Vita’s CPU overclocked to 500 MHz through a separate plugin. The author puts the speedup at about 5.3 times.
The current build lets you drag the conversation or use the D-pad to scroll the whole chat. The release includes a VPK and a checksum. The README explains how to prepare the model files separately.
Meteor works within a 512-token context window and caps replies at 128 tokens, so longer answers get cut off even when the model hasn’t finished. The author’s own tests ran out of space halfway through an omelet recipe.
The next update targets that cap. The author is working on a rolling KV cache, which would let the model discard older context and reuse that memory while it generates. The goal is responses thousands of tokens long without raising the roughly 56 MB KV cache. The cost is that the model gradually loses access to older parts of the chat. Configurable response lengths are also planned.
A 0.6B model on a handheld runs locally. It shows how small models behave on weak hardware, and the speed work decides whether longer chats are usable.